AI agents for business are moving from single-assistant workflows toward coordinated teams, and OpenAI’s September 2026 Navier–Stokes experiment may be the clearest signal yet.
On September 8, 2026, OpenAI published a proposed solution to one of the seven Millennium Prize Problems and described the system behind it: roughly 10,000 concurrent AI agents working in parallel. Fluid dynamics is the news hook. For business owners, marketers, and agencies, the architecture is the story.
OpenAI reports that a group of approximately 10,000 concurrent AI agents, powered by an unreleased internal model, produced a proposed proof for the Navier–Stokes existence and smoothness problem in roughly 88 hours, after which GPT-6 Astra spent about 17 more hours formalizing and verifying the proof in Lean. The business lesson is multi-agent orchestration: specialized groups exploring different approaches in parallel, a consolidation step that shares useful findings, and independent verification before anything is published. That pattern, not the mathematics, is what companies will adopt. One caveat matters. OpenAI has published a proposed solution, the Clay Mathematics Institute still lists the problem as unsolved, and independent review remains essential.
| Fact | What OpenAI Reported | Why It Matters to Business |
|---|---|---|
| Concurrent agents | “On the order of 10,000” in the group that produced the Navier–Stokes result | The work was divided across many specialized agents, not handled by one assistant |
| Time to reported result | About 88 hours after the first agents launched (September 1 to September 5, 2026) | Parallel exploration compresses research calendars |
| Lean formalization and verification | An additional 17 hours, performed via GPT-6 Astra | Verification was a separate step from discovery |
| Agent messages | 2.7 million during the Navier–Stokes effort | Agents communicated inside groups; coordination was designed in |
| Output tokens | Approximately 130 billion during the Navier–Stokes effort | Frontier research at this scale is expensive; businesses need smaller, targeted versions |
| Model used | An internal model OpenAI describes as “significantly more capable than GPT-6 Astra”; training began August 28, 2026 and was ongoing; not publicly available | Capability is rising quickly, but the model behind this result cannot be purchased today |
| Consolidation method | Codex was used to consolidate the most useful insights across agent groups | A dedicated integration step keeps parallel work from fragmenting |
| Millennium Prize status | Clay Mathematics Institute lists Navier–Stokes as “Unsolved” as of September 8, 2026; OpenAI says it does not intend to claim the prize | Treat the result as proposed until independent mathematicians confirm it |
Sources: OpenAI, “On the Navier–Stokes Millennium Prize Problem” (September 8, 2026); Clay Mathematics Institute, “Navier-Stokes Equation” problem page.
The Navier–Stokes equations describe how fluids such as air and water move. The Millennium Prize question, posed by the Clay Mathematics Institute in 2000, asks whether a three-dimensional fluid that starts out smooth can develop a “singularity,” meaning fluid speeds that grow without bound in finite time. The Clay Mathematics Institute’s Navier–Stokes problem page still listed the problem as unsolved at publication.
According to OpenAI’s Navier–Stokes publication, its system produced an analytical proof and a Lean formalization showing that a smooth fluid at rest, driven by a smooth external force and holding finite energy throughout, can develop a singularity in finite time. OpenAI says this establishes alternatives “C” and “D” in the official formulation, the disproof versions. These are OpenAI’s claims about its own work; the paper and Lean code are public so mathematicians can check them.
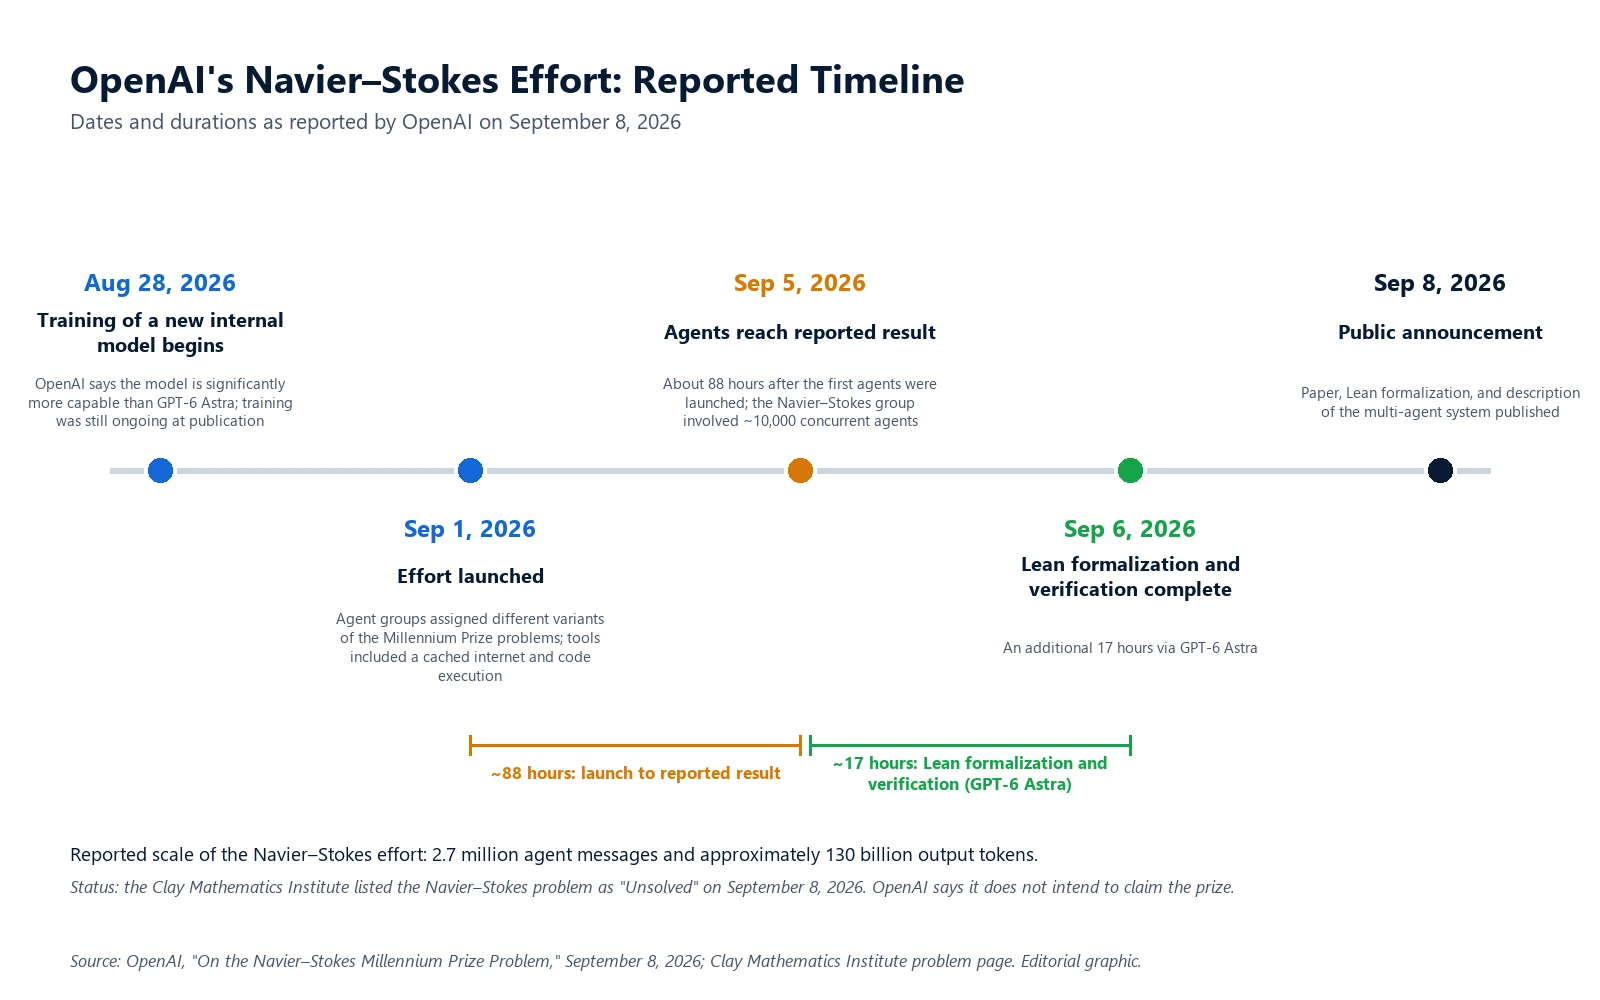
OpenAI’s account reads like an organizational chart. OpenAI launched the effort on September 1, 2026 and assigned different groups of agents different variants of the problem. Agents could communicate within their group, read a cached internet, and run code. The group that produced the Navier–Stokes result involved on the order of 10,000 concurrent agents. Human researchers set direction throughout. After a period of independent exploration, OpenAI used Codex to consolidate the most useful insights from each group and feed them back to the others, a step OpenAI calls cross-pollination. GPT-6 Astra then handled a separate formalization and verification stage in Lean.
The analogy for a business owner: one model is like hiring one highly capable worker. A coordinated multi-agent system is closer to creating a virtual organization of specialists that can investigate many paths simultaneously. That organization needs clear ownership, deliberate handoffs, and independent verification. Our analysis of AI agent coordination explains why agents sharing a workspace without that structure quietly undo each other’s work. No small business can or should reproduce 10,000 frontier research agents. The principle transfers. The headcount does not.
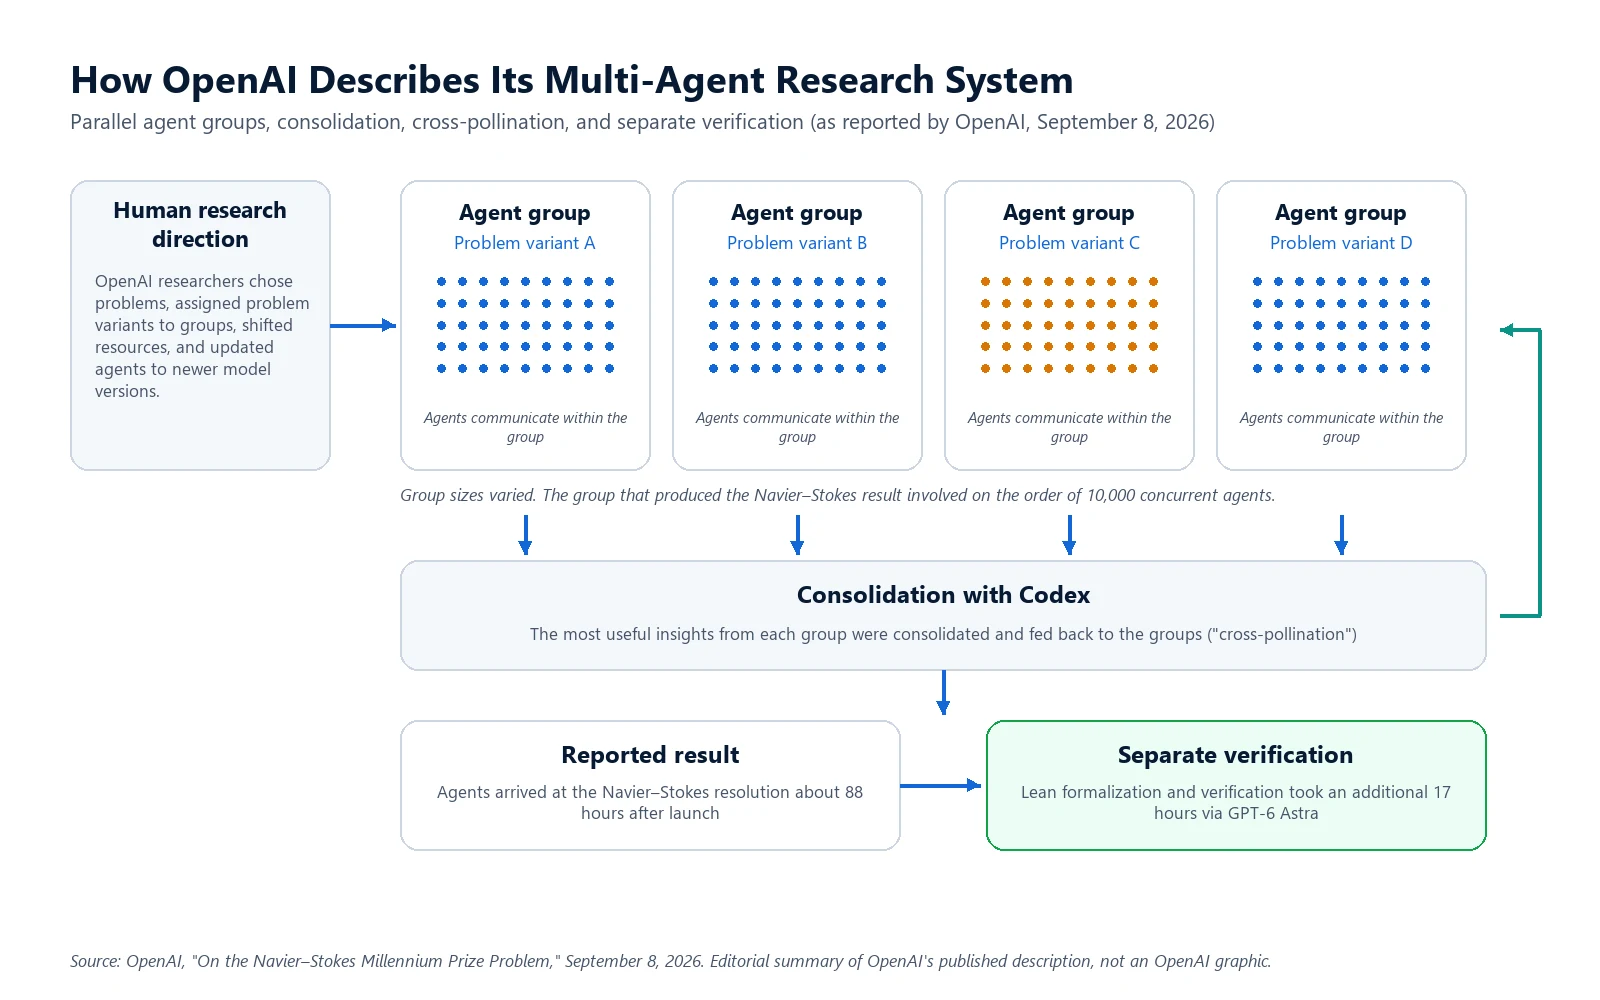
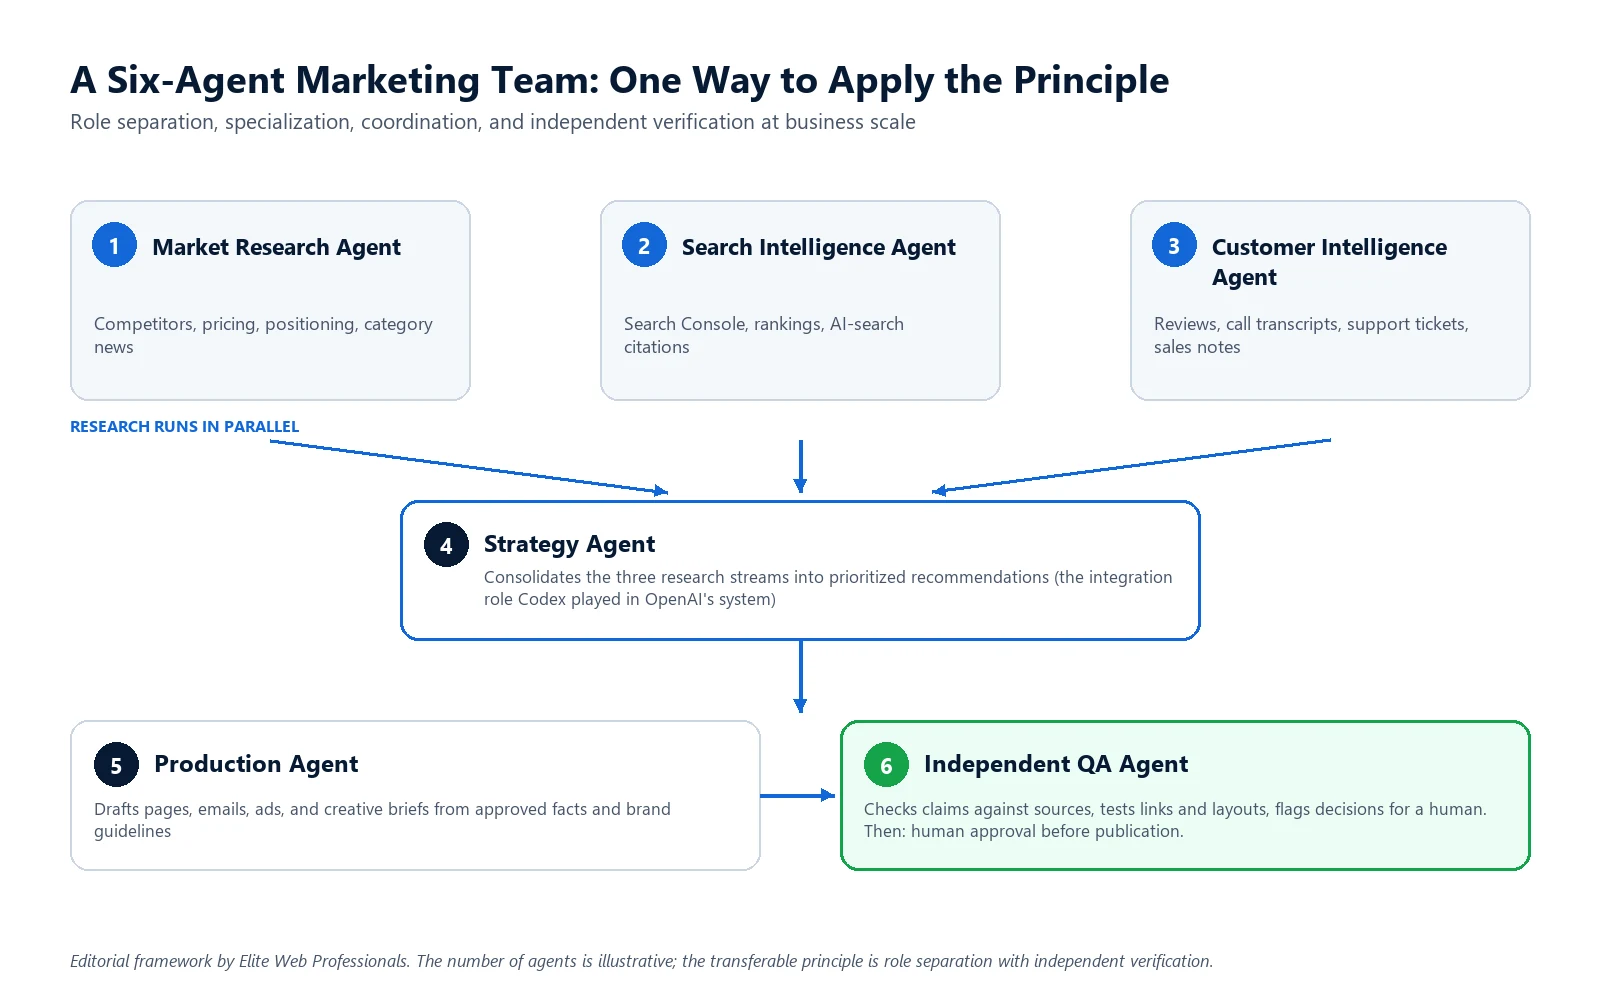
Most marketing departments still run a production line in which each stage waits for the one before it. The multi-agent pattern changes that shape. Competitor research, keyword research, Search Console analysis, customer-review analysis, content-gap analysis, offer development, landing-page analysis, creative ideation, conversion-rate analysis, fact checking, and QA can increasingly run as concurrent workstreams, each owned by an agent with a defined brief and data source, then consolidated by a strategist, as Codex consolidated findings for OpenAI.
The commercial implication: faster research, more experiments, better QA because verification is no longer cut, and a shorter distance between insight and live change.
Frontier models are turning into infrastructure. Soon most competitors will have access to similar models, and when everyone has the same engine, the engine stops being the advantage. What differentiates businesses is everything wrapped around the model: proprietary data, written instructions, tested workflows, connected tools, permission boundaries, defined agent roles, verification steps, customer knowledge, first-party evidence, and human judgment about what to publish or ship. The model becomes infrastructure. The operating system around the model becomes the advantage.
That operating system is what our guide to the AI workflow stack describes: models, agents, automation, data, websites, and review working as one connected system. OpenAI says its research system ran on an internal model “significantly more capable than GPT-6 Astra,” so raw capability keeps climbing; our overview of GPT-6 Astra for business covers what companies can do with the model they can buy today.
The point is not the number six. The point is role separation, specialization, coordination, and independent verification. Which tool owns each role is a separate decision; our AI agent decision matrix compares Codex, Claude Code, Gemini CLI, and OpenClaw.
When agents can generate and test ideas in parallel, generic content becomes nearly free, and free content is no advantage. What remains scarce is information competitors cannot generate: first-party data, customer interviews, call transcripts, verified reviews, documented case studies, original photos and video, your own test results, local expertise, and proprietary operating data.
In search, original evidence separates a page that repeats the consensus from a page that adds something new. In AI search, original evidence earns citations, because answer engines favor specific, verifiable, attributable facts, the core of AI Search Optimization. In sales, original evidence is the proof that closes. Agents can organize and amplify evidence; only your business can create it.
The announcement arrived with a dispute. OpenAI says a rumor that two Millennium Prize problems had been resolved triggered its September 1 effort, and that the rumor related to work by Tristan Buckmaster, a mathematics professor at New York University, and Levent Alpöge, an Anthropic employee. OpenAI says it contacted the two on September 6, learned they had resolved the forced Euler problem rather than Navier–Stokes, and recognizes their priority on that result.
OpenAI states that neither its researchers nor its agents saw the pair’s work before public release and that “no specific user data was accessed” to solve the problem. OpenAI adds that it cannot rule out that de-identified data from the researchers’ use of OpenAI products helped improve its models, while calling that unlikely.
CONFIRMED: the concurrent work, the rumor as OpenAI’s stated trigger, OpenAI’s denial of direct access, and OpenAI’s acknowledgment that de-identified usage data cannot be fully ruled out. DISPUTED / UNCONFIRMED: any claim that private research was accessed or taken. Public speculation is not proof that private research was stolen.
OpenAI’s current data-use policy states that content from consumer services such as ChatGPT may be used to train models unless the user opts out, while business products such as ChatGPT Team, ChatGPT Enterprise, and the API are not trained on by default. Every company adopting agents needs written policy covering confidential client data, proprietary research, unreleased products, source code, financial forecasts, prompts, internal strategy, employee access, model and provider selection, and data-retention settings.
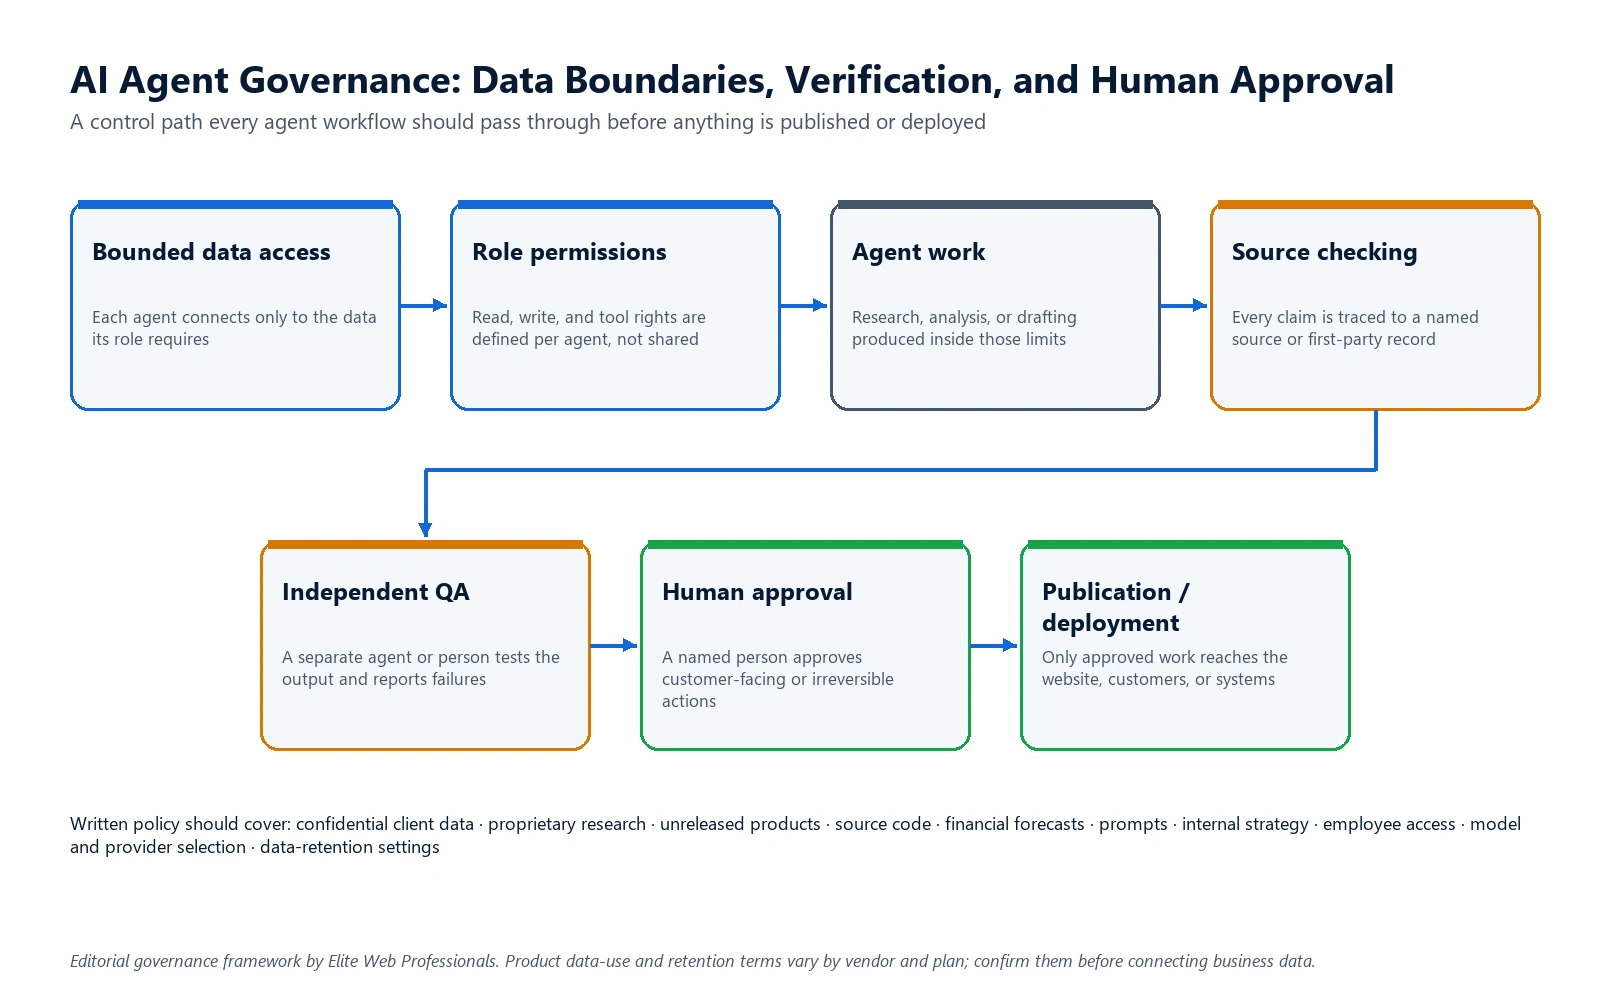
Two or three well-bounded agents with clear roles will outperform a swarm with none; no business needs thousands of agents to benefit from the pattern.
| Confirmed (publicly reported by OpenAI or Clay) | Still requires independent confirmation |
|---|---|
| OpenAI publicly reported the result on September 8, 2026 | Broader acceptance of the proof by the mathematical community |
| OpenAI published the paper “Finite Time Blowup for Navier–Stokes” | Official recognition by the Clay Mathematics Institute, which currently lists the problem as unsolved |
| OpenAI published a Lean formalization of the proof | Any Millennium Prize status; OpenAI says it does not intend to claim the prize |
| OpenAI reported the architecture and figures: ~10,000 agents, ~88 hours, 17 hours of Lean verification, 2.7 million messages, ~130 billion output tokens | Disputed or speculative allegations about private-data access and research priority |
AI agents for business will not eliminate the need for strategy, customer understanding, verification, or judgment; they will multiply the speed at which strong organizations can turn those things into action. The winners will be the organizations that learn to orchestrate intelligence, tools, data, agents, verification, and human judgment at their own scale.
AI is leverage, not a gimmick, and leverage only works when attached to something solid: a website built to convert, SEO and AI-search visibility that bring the right people to it, marketing systems that follow up, automation that removes waiting, analytics that tell the truth, and a human who verifies what goes out the door. Elite Web Professionals helps service businesses connect websites, SEO, AI search, automation, analytics, and AI-assisted workflows into systems designed to create visibility, leads, and measurable business performance. Orchestrate the pieces so the business can be visible, be found, and get chosen.
AI agents for business are software systems that use an AI model to complete defined tasks with tools and data, rather than only answering a prompt. An agent can read files, run analyses, draft work, and hand results to another agent or a person for review. In business, agents are typically assigned a role, such as research, production, or QA, and coordinated inside a workflow with defined data access and human approval.
No official resolution has been declared. OpenAI published a proposed solution and Lean formalization on September 8, 2026 that it says resolves the problem, but the Clay Mathematics Institute still lists Navier–Stokes as unsolved at the time of publication. Independent mathematical review and any formal prize-recognition process are separate matters, and OpenAI has said it does not intend to claim the Millennium Prize.
OpenAI says it divided agents into groups, gave each group a different variant of the problem, and let agents communicate within their group while using tools to read a cached copy of the internet and run code. The group that produced the Navier–Stokes result involved on the order of 10,000 concurrent agents. Codex consolidated the most useful insights across groups, the agents reached a result after about 88 hours, and GPT-6 Astra then spent roughly 17 hours on Lean formalization and verification.
Marketing research, strategy, production, and QA can run as parallel, specialized workstreams instead of a single sequential production chain. That means faster research, more experiments, more consistent quality checks, and a shorter time from insight to a live change. It also raises the value of original business evidence, because generic content becomes cheap to produce.
No. The transferable principle is role separation, coordination, and independent verification, not headcount. A small business or agency can apply the pattern with a handful of agents, each with a defined brief and bounded data access, plus human approval for customer-facing output.
AI agent orchestration is the design and management of how multiple AI agents, tools, data sources, and human checkpoints work together: which agent runs, with what inputs, in what order, how findings are consolidated, and who verifies the result. Orchestration is broader than communication, which is agents sharing information, and coordination, which is agents avoiding overlap.
Key risks include exposure of confidential data through prompts or connected tools, agents acting on unverified or fabricated information, overlapping agents undoing each other’s work, unclear accountability, and vendor data-use or retention settings that do not match company policy. Bounded data access, independent QA, human approval, and written governance address most of these risks.
 173 W. Wieuca Road Northeast #104
 customersupport@advertisingbusiness.org
 (770) 874-6085
 (770) 874-6085


 770-874-6085