 (770) 874-6085


 770-874-6085

Claude Fable 5.1 marketing workflows are worth testing only when they solve a difficult business problem better than the lower-cost model or process you already use. The correct test is a controlled workflow with an accountable reviewer, not seven generic prompts or a benchmark-driven stack change.
Quick Answer: When Is Fable 5.1 Worth Testing?
Test Fable when a lower-cost process repeatedly fails on difficult reasoning, source synthesis, or a long assignment where correction and delay are expensive. Anthropic positions Fable 5.1 for demanding reasoning and long-horizon work, while its model guidance says most workloads start with Opus 5. Large context is capacity, not proof of business value.
| Item | Confirmed position | Decision implication |
|---|---|---|
| Positioning | Demanding reasoning and long-horizon work | Use a baseline first |
| Price | $10 input / $50 output per MTok | Measure total cost |
| Context | 1M tokens | Curate the source set |
| Output | Up to 128K tokens | More text is not more useful |
| Approval | Human remains accountable | Never automate publication by default |
How to Compare a Model With the Process You Already Use
Freeze the task, source material, deadline, and acceptance criteria. Run the current model or human process, then run Fable with the same constraints. Score first-draft usefulness, factual accuracy, strategic insight, instruction compliance, brand voice, completion time, total cost, corrections, human-review time, and final business usefulness. Vendor benchmarks do not directly measure these outcomes.
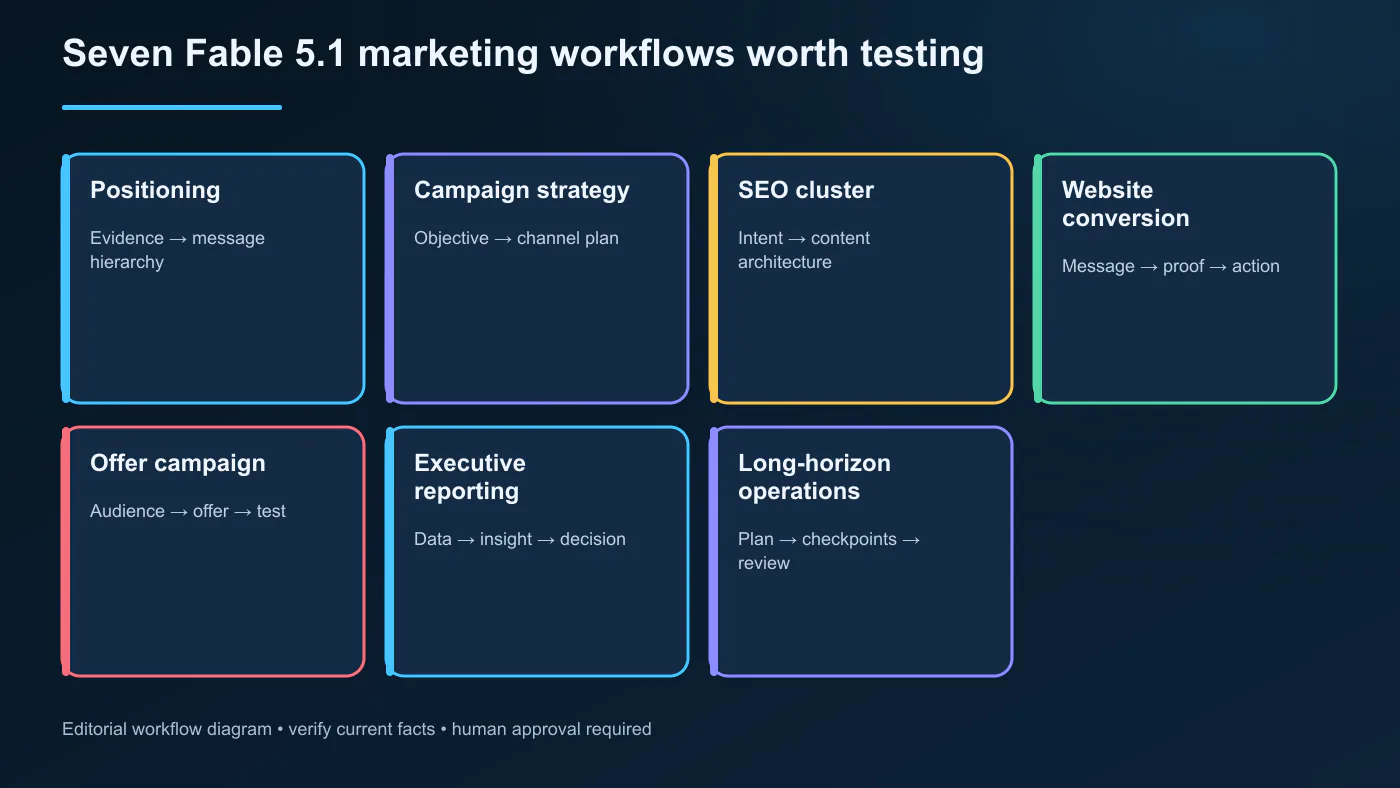
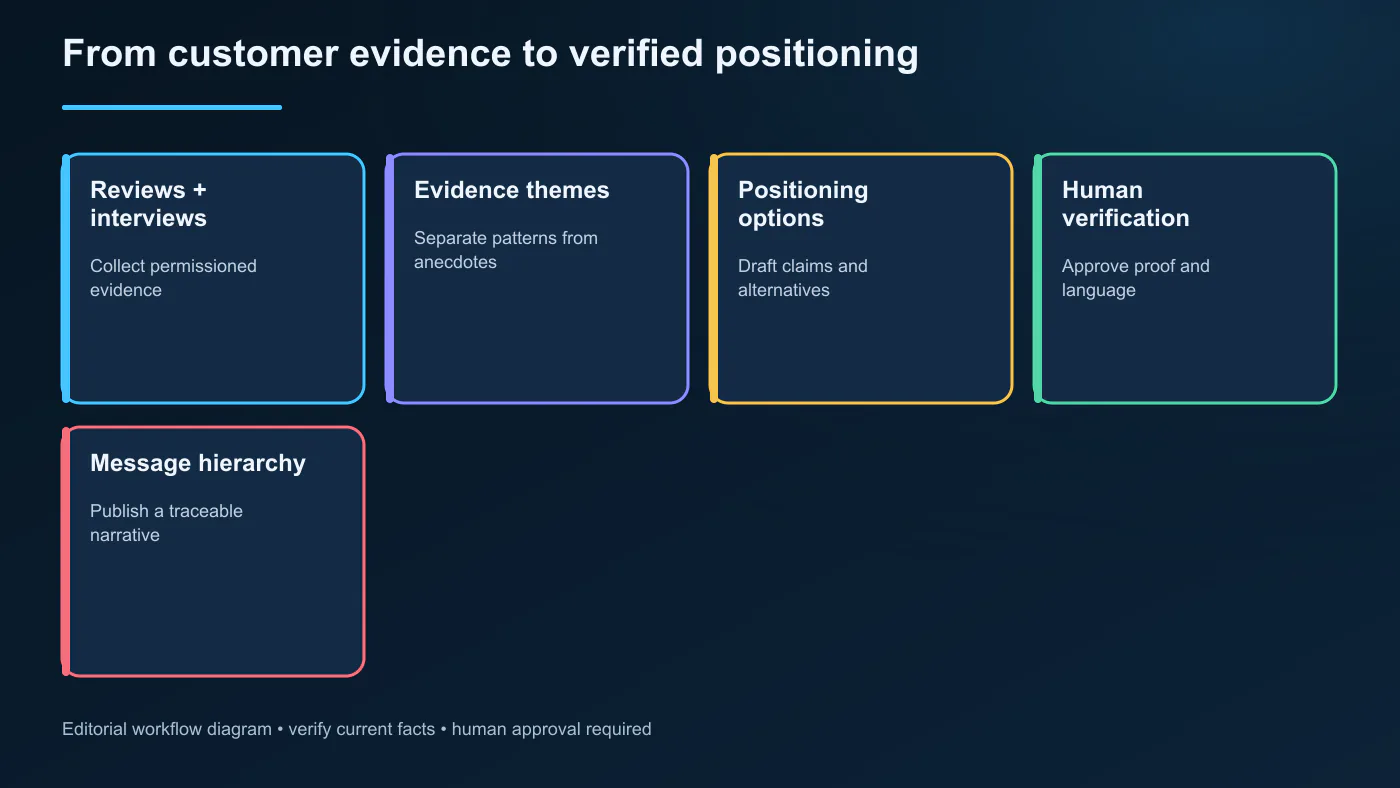
Workflow 1: Turn Customer Evidence Into Better Positioning
Business problem: Fragmented customer language obscures the buying reason.
Source material: Reviews, interviews, sales calls, objections, and verified outcomes.
Fable 5.1 assignment: Separate observations, themes, assumptions, and positioning options.
Finished deliverable: Evidence ledger and approved message hierarchy.
Human review gate: Verify claims, source use, brand fit, and approval before implementation.
KPI: Qualified lead rate and message-approval time.
Cheaper-model alternative: Opus or a human analyst with a tight evidence brief.
Workflow 2: Build a Research-Backed Campaign Strategy
Business problem: A campaign needs a coherent offer, audience, proof, and test plan.
Source material: Market research, competitor pages, customer evidence, offer economics.
Fable 5.1 assignment: Build a source-cited strategy with assumptions labeled.
Finished deliverable: Campaign brief, test matrix, and approval checklist.
Human review gate: Verify claims, source use, brand fit, and approval before implementation.
KPI: Offer conversion and cost per qualified lead.
Cheaper-model alternative: Opus with a constrained planning template.
Workflow 3: Audit and Refresh an SEO Content Cluster
Business problem: Existing pages and search data do not point to a single refresh order.
Source material: Crawl export, Search Console, analytics, posts, and internal-link map.
Fable 5.1 assignment: Identify intent gaps, consolidation risks, and a source-backed editorial queue.
Finished deliverable: Prioritized content-cluster plan with measurement plan.
Human review gate: Verify claims, source use, brand fit, and approval before implementation.
KPI: Indexed priority pages and qualified organic clicks.
Cheaper-model alternative: Opus with a structured data workbook.
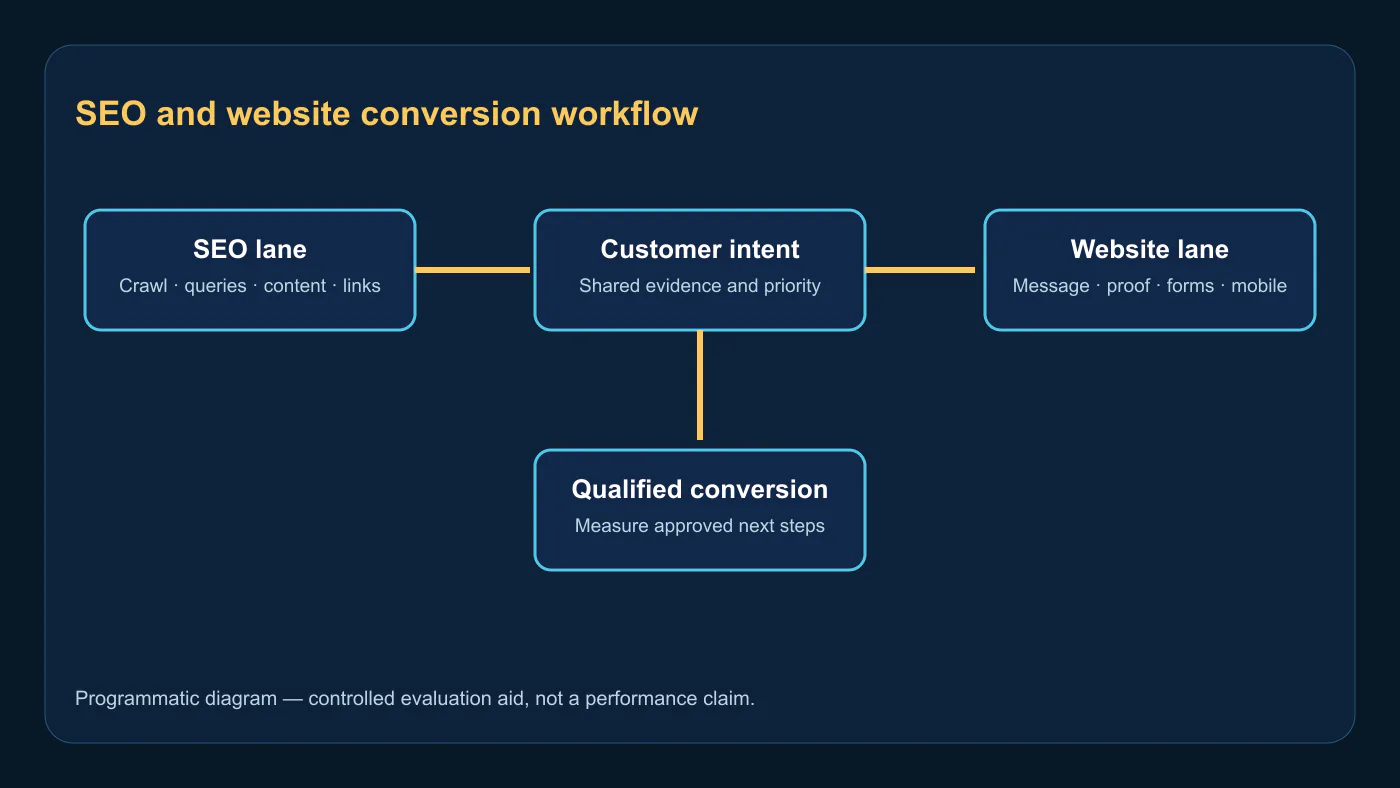
Workflow 4: Review a Website for Conversion and Message Gaps
Business problem: Traffic arrives but the proof, message, and next step do not align.
Source material: Website pages, recordings, forms, analytics, reviews, and call data.
Fable 5.1 assignment: Trace intent through message, proof, form friction, and measurement.
Finished deliverable: Annotated conversion brief and experiment backlog.
Human review gate: Verify claims, source use, brand fit, and approval before implementation.
KPI: Qualified form completion and call rate.
Cheaper-model alternative: Opus for a fixed-page heuristic review.
Workflow 5: Build a Multi-Channel Offer Campaign
Business problem: An offer must stay consistent across landing page, email, ads, and sales follow-up.
Source material: Approved positioning, offer terms, proof, audience, and channel constraints.
Fable 5.1 assignment: Create a governed asset plan with one claim register.
Finished deliverable: Channel map, approved drafts, and UTM plan.
Human review gate: Verify claims, source use, brand fit, and approval before implementation.
KPI: Qualified conversion by channel.
Cheaper-model alternative: Sonnet or Opus for execution after strategy is approved.
Workflow 6: Create an Executive Report, Spreadsheet, and Presentation
Business problem: Leaders need a concise decision from messy performance data.
Source material: Validated analytics, CRM export, spend data, and decision questions.
Fable 5.1 assignment: Reconcile the narrative to supplied numbers and label unknowns.
Finished deliverable: Executive report, spreadsheet outline, and slide narrative.
Human review gate: Verify claims, source use, brand fit, and approval before implementation.
KPI: Decision cycle time and data-correction count.
Cheaper-model alternative: Opus with a locked data dictionary.
Workflow 7: Run a Long-Horizon Marketing Operations Assignment
Business problem: A multi-week initiative risks losing sources, scope, and decision history.
Source material: Objective, plan, acceptance criteria, source register, changelog, and verification report.
Fable 5.1 assignment: Maintain a staged plan, flag exceptions, and produce evidence for review.
Finished deliverable: Workstream ledger with gated milestones.
Human review gate: Verify claims, source use, brand fit, and approval before implementation.
KPI: On-time approved milestone completion.
Cheaper-model alternative: Opus plus disciplined project files and human coordination.
What Not to Automate Without Approval
Do not automatically publish content, alter live accounts, approve legal or regulated claims, invent customer quotations, interpret unvalidated analytics, or represent credentials. Tools can prepare work; accountable reviewers decide what is true, safe, and ready.
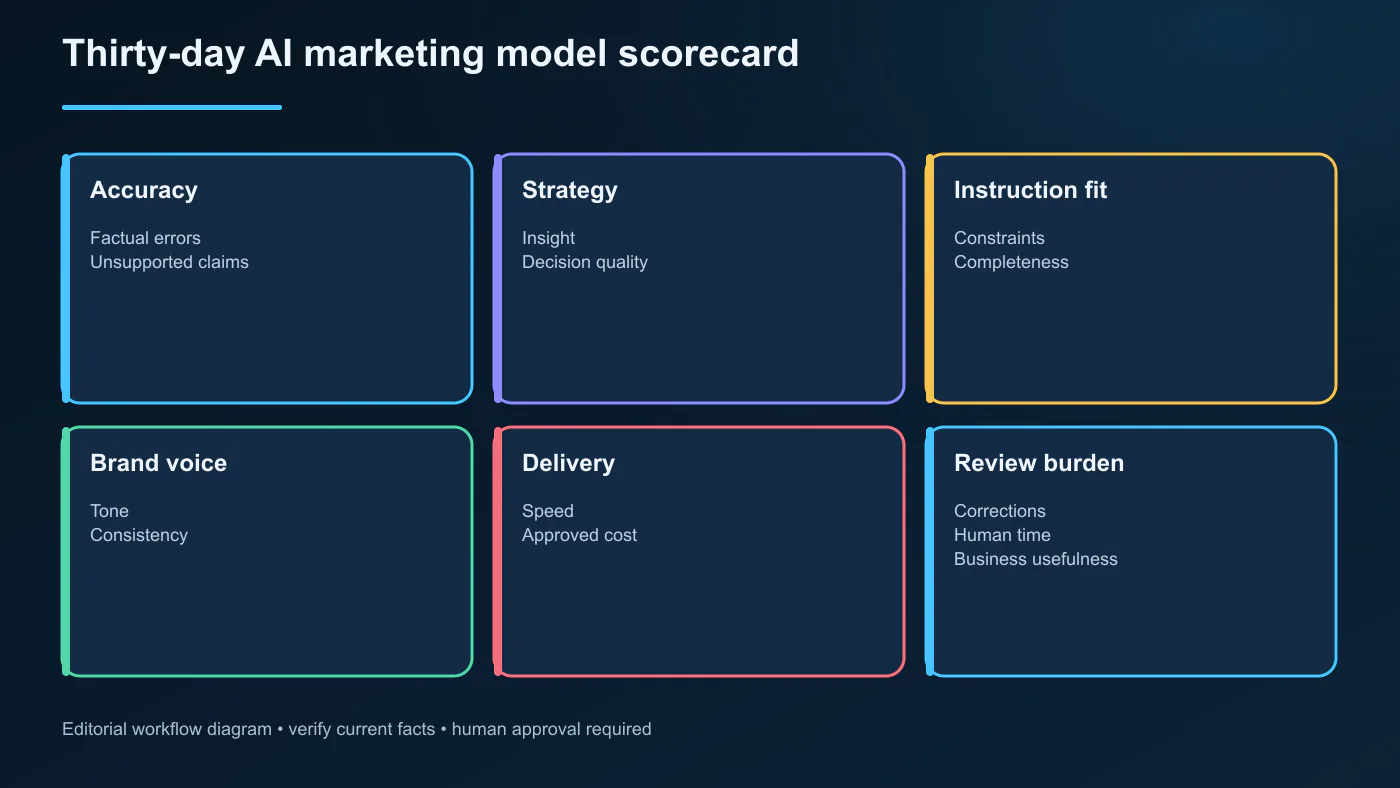
A 30-Day Fable 5.1 Marketing Scorecard
Run paired tests over representative work, not only the most impressive case. Keep numeric cells blank until a human validates results. If a lower-cost model plus a better brief matches the approved outcome, keep the lower-cost route. If Fable reduces costly corrections on difficult work, document that narrow escalation rule.
Claude Fable 5.1 marketing workflows should earn a permanent place in your stack through measurable improvements in approved output, not through benchmark excitement alone.
Measure the Finished Work Before You Change the Stack
Elite Web Professionals helps service businesses turn visibility into a measurable growth system. Evaluate the finished work, protect the evidence, and change the stack only when the approved result earns the cost.
Use AI search optimization, Atlanta web design, and AI and web-design planning to connect model evaluation to real customer outcomes.
Frequently Asked Questions
What marketing work is Claude Fable 5.1 best for?
Claude Fable 5.1 is best tested on demanding reasoning, difficult synthesis, and long-horizon work where a lower-cost baseline repeatedly misses the acceptance standard. Anthropic positions it for demanding reasoning and long-running agentic work; that positioning is not proof that it improves every marketing task or eliminates human review.
Is Fable 5.1 worth the cost for content marketing?
It can be worth testing when difficult research synthesis, planning coherence, or correction burden is the bottleneck, but it is not automatically worth the premium for content marketing. Compare the same brief and source set against a lower-cost baseline, then measure factual accuracy, brand voice, review time, and approved business usefulness.
Should Fable 5.1 write and publish marketing content automatically?
No. Fable can draft or structure work, but accountable people should verify marketing claims, customer quotations, legal assertions, analytics interpretation, credentials, and publication. A defined implementation layer and approval gate are required before any live account or content change is made.
What should an agency test before adopting Fable 5.1?
An agency should test a fixed source set, a lower-cost baseline, acceptance criteria, factual accuracy, strategic insight, instruction compliance, brand voice, completion time, total cost, corrections, review time, and final business usefulness. Keep the task bounded and run enough representative work to avoid adopting a model from one impressive example.
When should a marketer use a cheaper Claude model?
Use a cheaper model when the brief is clear, source material is manageable, the task is high-volume or routine, and the approved output is already within the correction budget. Anthropic says most workloads start with Opus 5; no model should be upgraded merely because it has a longer context window or a stronger benchmark claim.
Can Fable 5.1 create reports, spreadsheets, and presentations?
Yes, Anthropic positions Fable 5.1 for analysis carried through to a finished document, spreadsheet, or deck. That capability does not remove the need to verify numbers, sources, chart labels, claims, and presentation decisions before an executive audience or client receives the work.
How should marketers measure Claude Fable 5.1 results?
Measure Fable 5.1 against the current model or process using the same source material and acceptance criteria. Track first-draft usefulness, factual accuracy, strategic insight, instruction compliance, brand voice, completion time, total cost, correction count, human-review time, and final business usefulness.
Related Reading
Our Astra marketing-agency workflow guide separates strategy, production, approval, and public verification.
For an accepted-task cost framework, see our GPT-6 Astra pricing and API guide.
Sources
- Anthropic: Introducing Claude Fable 5.1 and Claude Mythos 5.1
- Claude Platform: Claude Fable 5.1 model overview
- Claude Platform: Claude Opus 5 model overview
- Claude Platform: Choosing the right model
- Claude Platform: Pricing and prompt caching
- Claude Platform: Effort controls
Watchlist
September 3, 2026: Recheck availability, list pricing, cache terms, model documentation, independent evaluations, and any first-party marketing tests before changing dates, charts, FAQs, schema, or metadata.
KPIs to Track
- Organic impressions and click-through rate for the target query
- Engagement with the decision table and workflow modules
- Clicks to related AI-search and web-design resources
- Qualified AI strategy, SEO, and website inquiries
- Assisted conversions from this series

 customersupport@advertisingbusiness.org
 (770) 874-6085